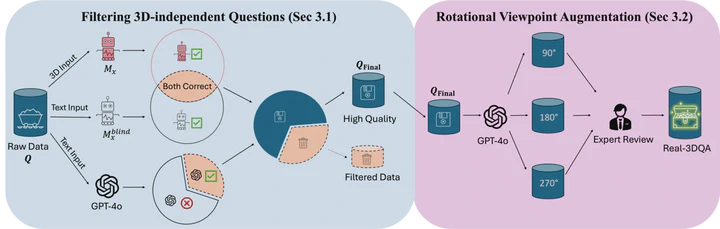
 Constructing Real-3DQA through question filtering and viewpoint augmentation.
Abstract
Text-only models can match or surpass 3D language models on SQA3D, suggesting that language shortcuts can obscure weaknesses in spatial reasoning. Real-3DQA filters easy-to-guess questions and introduces a taxonomy of 3D reasoning tasks. A 3D-reweighted training objective encourages models to use visual geometry and improves spatial reasoning performance.
Type
Publication
International Conference on Learning Representations (ICLR) 2026